Tenant settings
Configure AI behavior, access, integrations, branding, and model resources for one tenant.
The Administration workspace groups tenant-wide controls under the selected Keycloak Organization. These settings affect users and workloads in that tenant rather than the signed-in administrator alone.
Select a tenant
You must administer the selected tenant to open its settings in Portal. Platform-administrator status alone does not grant administration of every tenant.
- Switch from OmniChat to Administration.
- Select the tenant in the tenant selector under Tenant in the sidebar.
- Select the organization whose configuration you want to inspect or change.
Tenant pages remain disabled until a tenant is selected. The page header identifies the tenant currently being managed. Changing the selection reloads the current administration area with the new tenant context.
Available settings
The following permissions describe the API operations behind each area. Portal also requires administrator authority in the selected tenant; the catalogue lists the exact scope and implications.
| Area | Required operation permissions |
|---|---|
| Analytics and Budgets | tenant.usage.read to read usage and balances; tenant.usage.budget_manage to set caps. See Review tenant usage and Manage monthly BCU allowances and caps. |
| Deep Research | tenant.read to inspect limits; tenant.update to save or reset |
| Code sandbox | tenant.read to inspect settings; tenant.update to turn the sandbox on or off and to save or reset its limits |
| General | tenant.read to read safe settings; tenant.update for general changes; tenant.embedding.read / tenant.embedding.update for the embedding model and document processing settings |
| Members | tenant.member.list for directory reads; identity-management controls also need tenant.group.list; separate add, create-local and remove permissions |
| Groups | tenant.group.list for directory reads; identity-management controls also need tenant.member.list; separate create, update, delete and membership-management permissions |
| Roles | tenant.role.list to inspect definitions; separate create, update, delete, assign and revoke permissions |
| Collections | storage.space.list and storage.space.read for collection inspection; tenant.embedding.read for embedding collections |
| Theme | tenant.branding.update |
| Service Desk | tenant.service_desk.read for configuration; tenant.service_desk.update for changes |
| Integrations | tenant.provider.read and tenant.provider.manage |
| Allowed Resource Profiles | tenant.runtime_profile.list plus platform.runtime_profile.read to inspect choices; only platform administrators change the allowed set and define GPU profiles |
Current tenant members already have tenant.embedding.read, tenant.service_desk.read, tenant.member.list and tenant.group.list for uploads and collaboration. These reads do not grant configuration changes, membership management or Administration entry.
Starting a reindex, and previewing what it would rebuild, requires both tenant.embedding.update and tenant.reindex.start; progress and cancellation use tenant.reindex.read and tenant.reindex.cancel. A tenant-administrator assignment does not automatically supply inference-role permissions for model presets or runtime profiles.
General
Open Administration → Tenant → General to manage chat defaults, retrieval, and document-processing behavior for the selected tenant. The page shows its sections in this order: Chat, Document Processing, Vision Model, Retrieval, Reranker, and File settings.
Chat settings
Default model or GPT sets the tenant's default for new chats. A member's new chat starts with the model or Agent that member last used successfully; the tenant default applies when that choice is unavailable or the member has none. Select a chat model or an Agent, or No tenant default. Selecting an Agent requires read access to it. The setting does not change existing chats or a choice a member makes in the selector. When the saved model or Agent is no longer available, the field shows Configured selection is unavailable, and new chats skip it.
Automatic chat titles replaces a new chat's first-message title with a short generated title after the first successful answer. Automatic titles are disabled by default.
- Title model selects one of the tenant's available chat models. Disabled turns generation off and keeps the first message as the title.
- Instructions is the plain-text prompt sent to the title model, without template variables. Use default instructions restores the default, which asks for a title of 3 to 8 words. Disabling automatic titles keeps the instructions.
The title model is asked once per chat. If generation fails or returns no text, the first-message title stays. A title that a member sets with Rename is never replaced, and Service Desk chats are not renamed. Members see the result in the chat history.
Concurrent chat answers (API only)
Two settings limit how many chat answers can be generating at the same time in the tenant. Portal has no control for them: change them with PATCH /v1/config in the chat section, which requires tenant.update.
| Setting | Default | Accepted range |
|---|---|---|
max_concurrent_generations_per_tenant | 32 | 1 to 32 |
max_concurrent_generations_per_user | 5 | 1 to 32 |
- Each BullSequana AI API process counts separately. With two API replicas, the tenant can have up to twice each limit generating, depending on which replica serves each request.
- Each API process also answers at most 40 chats at once across all tenants. A chat beyond that gets the same 503.
- A missing or
nullvalue uses the default. - A chat over a limit fails at once with HTTP 503
chat_generation_unavailable("Chat is busy. Try again shortly."). It can be sent again when another answer finishes. A second request for a chat that is still answering gets HTTP 409chat_turn_conflictinstead. - Each answer being generated holds a database connection; see the PostgreSQL connection budget.
Reranker
The reranker is an optional retrieval step that reorders search results before they are passed to the model. Administrators can enable or disable it, select the reranker model, and set Reranker Top N from 1 to 50.
A model and Top N value must be configured before the reranker can be enabled.
Document processing and reindexing
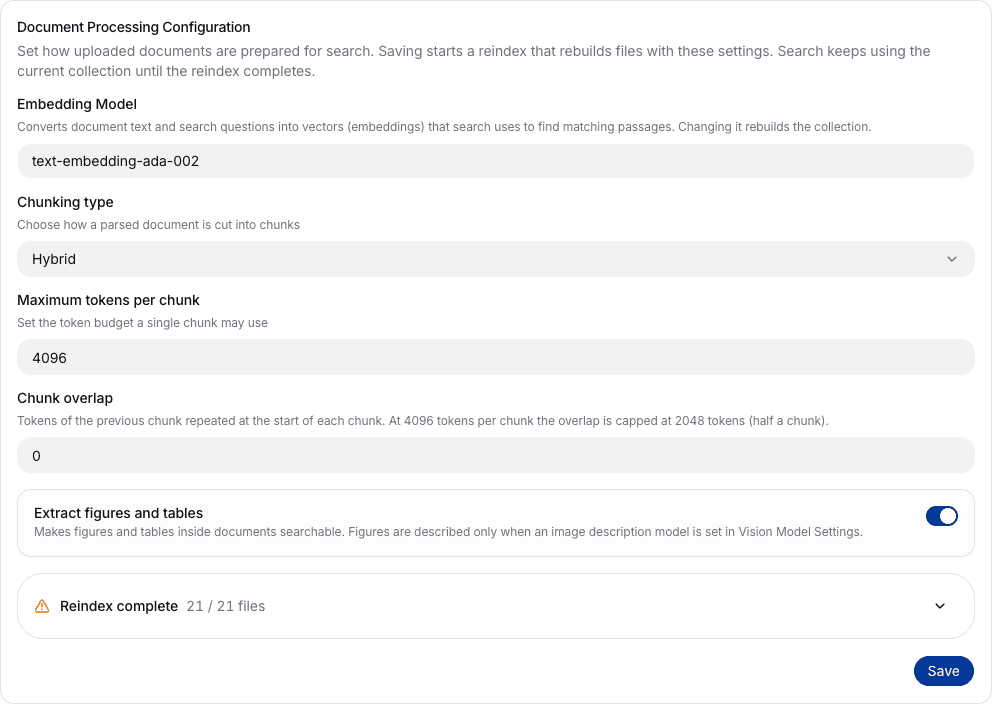
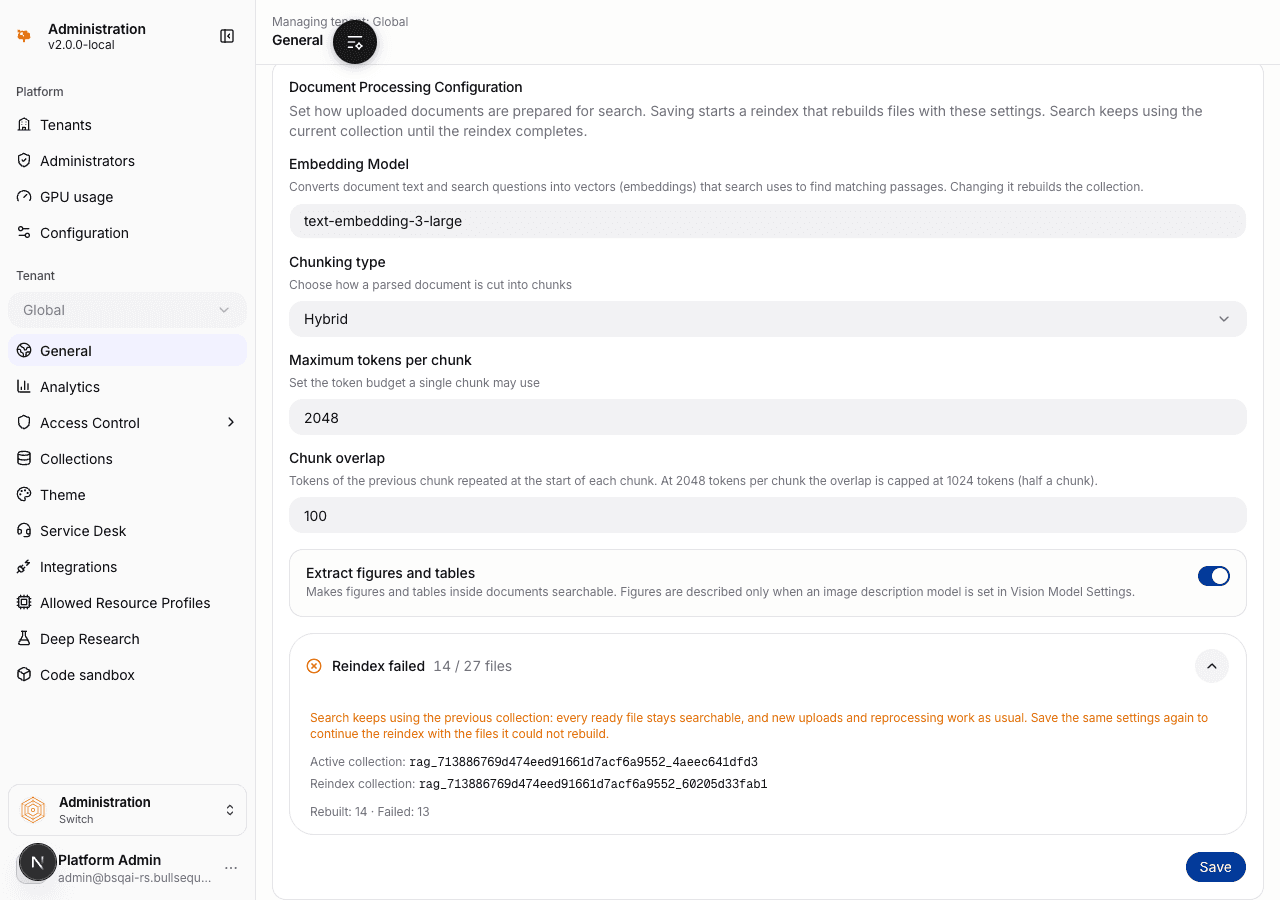
The Document Processing Settings card sets how the tenant's files are built for search: the embedding model, and how documents are split into chunks. Administrators with tenant.embedding.update see the card. It shows the values the library is built with, or the defaults when nothing has been saved yet. Its description reads: "Set how uploaded documents are prepared for search. Saving starts a reindex that rebuilds files with these settings. Search keeps using the current collection until the reindex completes."
| Field | API field | Default | What a change rebuilds in the reindex |
|---|---|---|---|
| Embedding Model | model | None | Embeds every file's saved chunks again |
| Chunking type | chunking_type | hybrid | Parses the text of every document again |
| Maximum tokens per chunk | max_tokens | 1024 | Parses the text of every file again |
| Chunk overlap | chunk_overlap_tokens | 0 | Embeds every file's saved chunks again |
| Extract figures and tables | extract_artifacts | On | On: extracts figures and tables only from files that lack them. Off: leaves them out of search |
The defaults apply to a new tenant. A tenant that existed before these settings could be saved keeps the chunking type, chunk size, and figure setting it had, with 4,096 tokens per chunk when it never changed the size, and no overlap.
- Chunking type applies to the documents Docling parses: PDF, Word, PowerPoint, Excel, CSV, and Markdown files. Hybrid merges document structure with a token budget, so chunks stay close to the configured size. Hierarchical follows the document outline only, so chunk sizes vary with the sections and the maximum tokens per chunk apply to text files only. Plain text, code, VTT, and JSON files are split by paragraphs up to the chunk size, whatever the chunking type.
- Maximum tokens per chunk is the token budget of one text chunk, from 1 to 8,192. The API refuses a larger value in a request with
422. A larger value stored before this limit applied keeps working. Each figure, table, and image description is one chunk, whatever the chunk size. A figure, table, image description, or text chunk over 60,000 bytes of UTF-8 text, about 60,000 characters, is stored in parts, because the vector store holds at most 65,535 bytes per chunk. Each part of a table repeats its caption, header row, and separator line. - Chunk overlap is the number of tokens of the previous text chunk repeated at the start of each text chunk, from 0 to half the chunk size, rounded down. The card shows the limit for the current chunk size, and the API refuses a larger value with
422and the error codechunk_overlap_too_large. The repeated text starts at a word boundary and is part of the stored chunk, so search results and chat context show it. Figures, tables, and image descriptions get no overlap and give none. - Extract figures and tables adds the figures and tables inside documents to search, one chunk each. Figures are described only when an image description model is set under Vision model; without one, a figure is found by its caption and the text inside it. Turned off, they are left out of search and cannot be downloaded by their
artifact_id. Turning it on again restores them from the saved chunks, without extracting them again.
The BSQAI API measures the embedding model's output dimension by embedding one text with it. The backend creates the tenant's collection with a generated name and records the model, its dimension, and the document processing values; administrators do not enter a collection name or a dimension.
A tenant's first save takes effect at once and creates the collection, without a reindex. After that, Save opens Apply these settings? with this description: "A reindex rebuilds the files of this tenant with these settings. Search keeps using the current collection until the reindex completes. Files cannot be reprocessed during the reindex." Two more paragraphs explain what each file reuses and how uploads and deletes during the reindex change its count:
Each file reuses what it already has: a new embedding model or overlap indexes it again, while a new chunk size or chunking type extracts its text again. Missing figures, tables and image descriptions are retried.
Files uploaded during the reindex are added to the new collection automatically and increase the final count; files deleted during it decrease it.
Below it, the dialog counts the tenant's files:
- Rebuild n files: the ready files that are not yet in the collection the reindex fills.
- Reprocess n failed files: the failed files that are processed again in full when the reindex completes. The line shows only when there are any. Image files count only when an image description model is set, and a file whose own upload or reprocess is still running is left to that run.
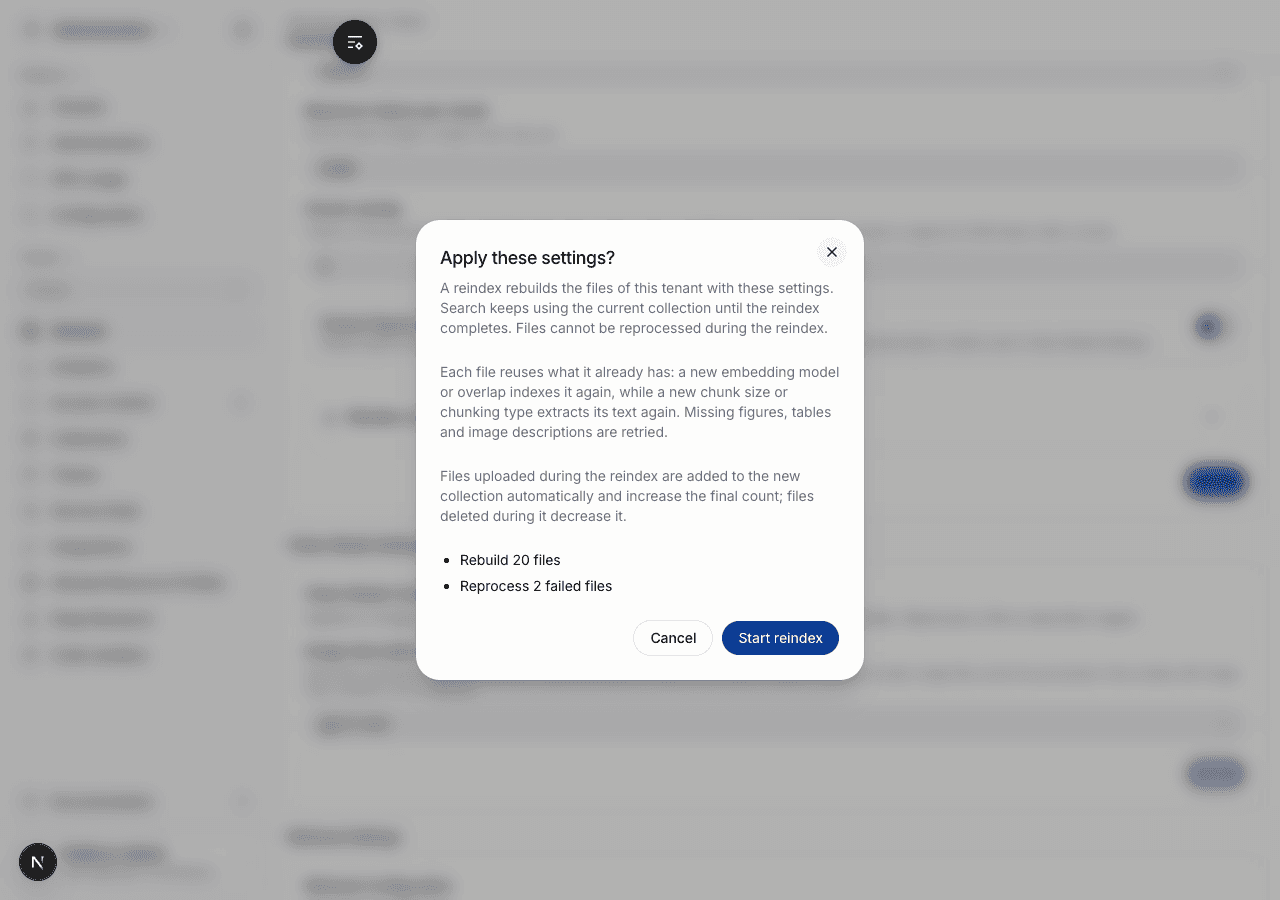
The counts come from the platform's database and are exact at the moment of saving; the dialog calls no model. When there is nothing to rebuild or reprocess, the dialog shows "No files need to be rebuilt or reprocessed." Start reindex starts the reindex into a new tenant-scoped collection; Cancel closes the dialog and changes nothing.
A reindex is the only way to change these settings: PATCH /v1/config refuses an embedding or document_processing section with 422, and Reset to default keeps both. When the model cannot be found, or does not return an embedding, Start reindex does not start the reindex, the page shows the error, and nothing changes. Files uploaded or reprocessed through the API with their own values keep those values through a reindex; only the embedding model changes for them.
Through the API, POST /v1/config/embedding/reindex/preview returns the same counts as rebuild and reprocess, and changes nothing. POST /v1/config/embedding/reindex/start starts the reindex. Both take model and, optionally, chunking_type, max_tokens, chunk_overlap_tokens, and extract_artifacts; an omitted value keeps the one the library is built with. With BSQAI_BASE_URL set to https://api.<platform-domain>/v1, this request keeps the model and sets an overlap of 100 tokens:
curl --fail-with-body -X POST "$BSQAI_BASE_URL/config/embedding/reindex/start" \
  -H "Authorization: Bearer $BSQAI_TOKEN" \
  -H "X-Tenant-Id: $BSQAI_TENANT_ID" \
  -H "Content-Type: application/json" \
  -d '{"model":"<current-embedding-model>","chunk_overlap_tokens":100}'
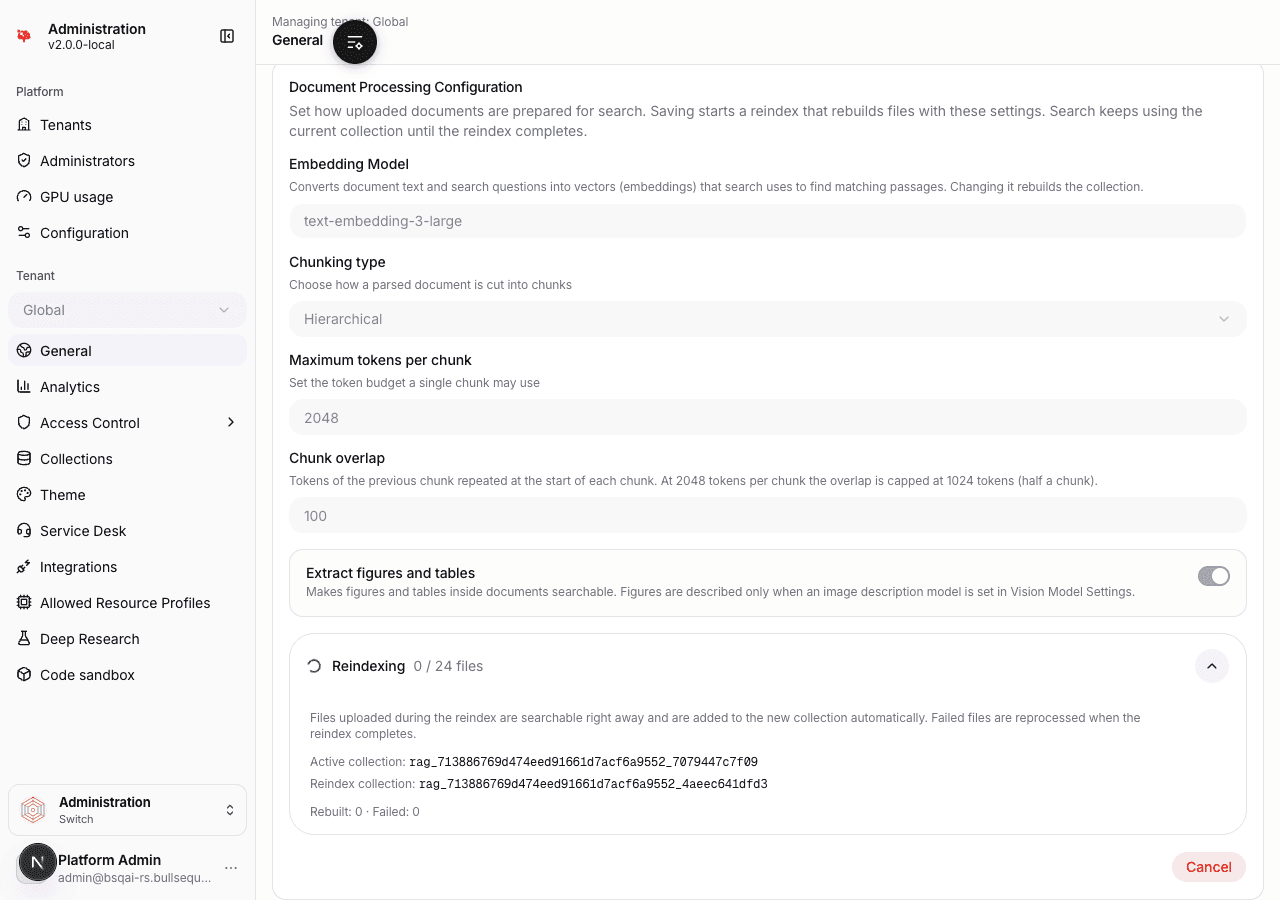
While the reindex runs, the card shows Reindexing with the number of files already in the new collection out of the total, for example 3 / 4 files. The total is the tenant's ready files at that moment: a file uploaded during the reindex adds one to both numbers, and a deleted file drops out of both. Expanding the panel shows the Active collection, the Reindex collection when it differs from it, the line Rebuilt: x · Failed: y, and a note on what the current state means for search and uploads. During the reindex the note reads: "Files uploaded during the reindex are searchable right away and are added to the new collection automatically. Failed files are reprocessed when the reindex completes." The fields are locked, and Cancel replaces Save to stop the reindex.
Search keeps using the active collection until the reindex completes. Files whose text or figures are extracted again are rebuilt during the reindex and stay searchable meanwhile. Files uploaded during the reindex are written to both collections, each with its own settings, and show the green Ready for search badge as soon as they are ready. Users cannot reprocess or retry files while a reindex runs; uploads stay possible.
When the reindex ends, the panel shows one of these states:
| Panel | What it means | What to do |
|---|---|---|
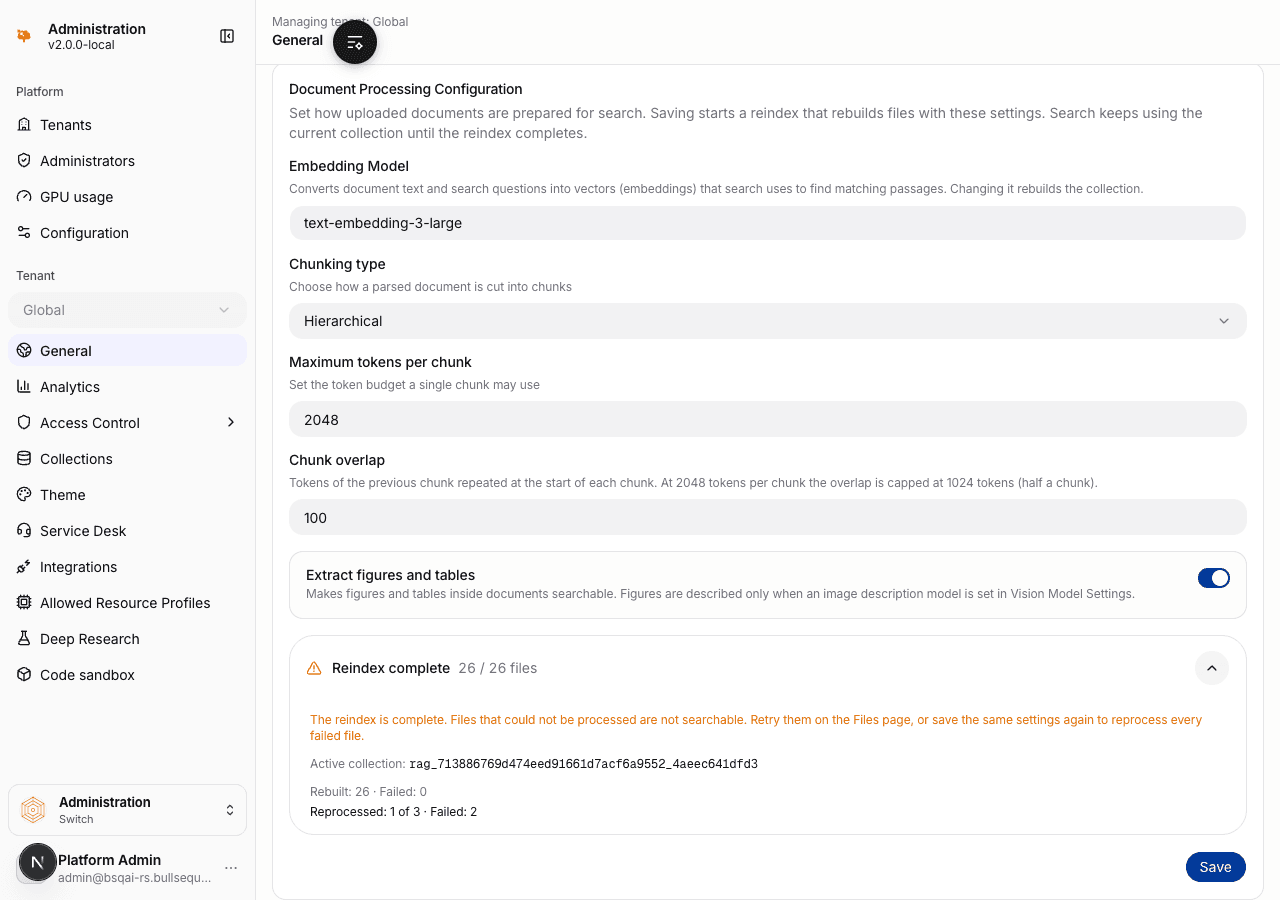
| Reindex complete | Search uses the new model and settings, and the previous collection is deleted. Files the reindex could not rebuild, and files whose processing failed earlier, are reprocessed. While that runs, the title adds Reprocessing and the number of files. A second line then shows Reprocessed: n of m · Failed: k. | Nothing, unless an amber warning icon shows. It means some files failed again and are not searchable. Retry them in Files, or save the same settings again to reprocess every failed file. |
| Reindex failed | The reindex could not rebuild a file, or it stopped. A file whose text cannot be extracted again, for example while Docling is unavailable, fails the reindex too. The note reads: "Search keeps using the previous collection: every ready file stays searchable, and new uploads and reprocessing work as usual." Hovering over the icon shows the error. | Correct the cause, then save the same settings again. The reindex continues with the files it could not rebuild. |
| Reindex cancelled | The administrator cancelled the reindex. Search keeps using the previous collection: every ready file stays searchable, files uploaded during the reindex included, and new uploads and reprocessing work as usual. The new collection is deleted, and the card returns to the model and settings search uses. | Nothing. |
A reindex reuses what each file already has:
- A model or overlap change embeds each file's saved chunks again, without parsing.
- A chunk size or chunking type change parses each file's text again: with Docling for documents, locally for plain text, code, VTT, and JSON. Image files are never parsed again. Each file keeps the text chunks of every chunk size and type it was built with, so returning to one used before reuses them without parsing again. A file processed before files kept their chunks per setting has only the chunks of the values it was built with; after a change, returning to those values parses it once more.
- Figures, tables, and image descriptions are reused from the file's earlier chunks, whatever the chunk size. A reindex with figures and tables on extracts them only from files where they were never extracted or the extraction failed.
- A reindex describes no image file again. When a vision model is set, it describes the pictures of PDF, Word, PowerPoint, and Excel files that have no description yet; existing descriptions are kept as they are.
The full processing after a completed reindex parses documents or describes standalone images, then chunks and embeds them, with the tenant's settings or the values a file was uploaded with. It is best effort and uses the default OCR settings. Files whose processing fails again keep Retry indexing in Files.
Saving the model and settings that search already uses runs a repair reindex. It rebuilds only the ready files missing from the active collection, which is what Rebuild n files counts, and reprocesses failed files. It keeps the active collection. When an earlier reindex to other settings failed, its collection is deleted, so saving those settings again starts the reindex from the beginning.
When a reindex stops without recording its result, the platform records it as failed within minutes. Saving the same settings again continues it. A file whose processing stopped is also marked failed, so it can be retried.
Docling splits documents into chunks with the tokenizer of the active embedding model; there is no separate tokenizer setting. The chunk overlap, and the chunk size of files split locally, are counted with the cl100k_base tokenizer. When Docling cannot load that tokenizer, the page shows a warning that names it and states what Docling chunks with instead: another tokenizer, or the document's structure. Documents are still indexed, but chunk sizes are approximate. To chunk with the exact tokenizer, deploy the embedding model on the platform, or ask the platform operator to give the BSQAI API access to a Hugging Face mirror. The same status is available from GET /v1/config/embedding/chunker-tokenizer, which requires tenant.read and tenant.embedding.read.
Retrieval
Retrieval K controls how many document chunks search returns as RAG context. The accepted range is 1 to 50, with a default of 3.
Search Mode selects Hybrid (the default) or Dense. Hybrid combines embedding similarity with BM25 keyword matching; Dense uses embedding similarity alone. Ranking merge constant (rrf_k) controls hybrid ranking fusion, from 1 to 1,000 with a default of 60. Higher values favor chunks appearing in both rankings. Keep the default unless you are measuring retrieval quality; it is independent of the number of returned chunks.
Saving retrieval settings requires tenant.update. Hybrid needs a collection created with the BM25 sparse field. Changing this setting does not upgrade an existing collection's schema. See retrieval compatibility and recovery.
Web search
The active provider determines which configured integration powers the Web search switch under the chat composer's Tools button and the web_search tool used by supported Agents. Select the active provider, and manage provider credentials and connection settings, under Integrations.
File size
The maximum file size setting controls the upload limit applied by the Files pipeline. The value is configured in megabytes.
Vision model
In Portal, the Vision Model Settings section of Administration → Tenant → General holds the Image description model picker. Its card states: "Applies to images described from now on. Existing descriptions are kept through a reindex. Reprocess a file to describe it again." Saving the model starts no reindex. Only chat models with image input enabled can be selected; other models are greyed out with "Image input is not enabled for this model". Not configured clears the setting. When the saved model no longer exists, or no longer has image input enabled, the picker shows a red hint asking for another model.
A model deployed through Studio does not have image input enabled automatically. Enable image input for its route first, with the capabilities button in Studio → Model routing.
Tenant administrators can also configure image ingestion through PATCH /v1/config, using a JWT with tenant.read and tenant.update in the selected tenant. GET /v1/config requires tenant.read. Follow API authentication and tenant selection.
vision.image_description_model selects a model-route alias and defaults to null. Use the alias, not the route ID or upstream model ID unless it is also the alias. The model is required for standalone PNG, JPEG, and WebP ingestion and optional for descriptions of extracted document pictures.
The API accepts only a route whose image input is enabled (supports_vision=true). An unknown alias, or a route with supports_vision false or not set, is rejected with HTTP 400, error code invalid_image_description_config, and param vision.image_description_model. The check runs only when the setting changes, so a saved model can later lose image input or disappear. The selected connection must support the image request and be reachable from the file-event worker. If the connection targets a model gateway, that gateway must expose a vision-capable model; Docling's own vision-model packaging does not supply this capability.
With BSQAI_BASE_URL set to https://api.<platform-domain>/v1, save the alias supplied by the administrator:
curl --fail-with-body -X PATCH "$BSQAI_BASE_URL/config" \
  -H "Authorization: Bearer $BSQAI_TOKEN" \
  -H "X-Tenant-Id: $BSQAI_TENANT_ID" \
  -H "Content-Type: application/json" \
  -d '{"vision":{"image_description_model":"<vision-route-alias>"}}'
Check the returned configuration, then upload a supported image and verify it becomes ready for search: stage available with upload_failed set to false. Upload and reprocess requests cannot override this tenant setting. Setting it back to null disables new document-picture descriptions and makes standalone image ingestion fail at the describing_pictures stage; it does not remove descriptions already indexed.
Document-picture descriptions require Extract figures and tables, a document processing setting, and a configured description model. Picture-description failures keep available extracted text or captions, and the file is marked with the pictures_not_described upload warning. Without a description model, documents get no picture warning. Standalone images bypass Docling and do not depend on the figure-extraction or OCR settings.
A new model describes only images and pictures processed from then on. A reindex keeps every existing description and describes only pictures that have none. To describe a file again with the new model, reprocess it.
Reset configuration
Reset to default restores the selected tenant's system configuration to backend defaults. The portal requires confirmation before applying the reset. The reset keeps three settings: the embedding model and the document processing settings, because changing them needs a reindex, and the code sandbox switch, so a sandbox turned off stays off.
Deep Research
Open Administration → Tenant → Deep Research to set limits for new research runs. Reading settings uses tenant.read; saving or resetting them uses tenant.update.
| Control | Effect |
|---|---|
| Max searches | Caps the planner's search queries. |
| Search concurrency | Limits searches running at the same time. |
| Max sources | Caps sources retained for synthesis. |
| Max research rounds | Caps additional searches to fill coverage gaps; 0 disables extra rounds. |
| Run deadline | Sets the time available for searching and writing the report, in minutes. |
| Clarify timeout | Sets the wait for answers before continuing with available information, in minutes. |
| Plan approval timeout | Sets the wait before the original plan runs automatically, in minutes. |
| Fetch max | Caps a fetched page's size, in KB. |
| Fetch concurrency | Limits simultaneous page fetches. |
| Fetch timeout | Limits each page fetch, in seconds. |
| Coverage gate | Reports planned topics with insufficient sources and drives extra research when rounds are enabled. |
| Screen citation URLs | Flags citation URLs absent from the collected reference set. |
The page displays the installation's defaults. A blank numeric field removes the tenant override; Reset to defaults removes all overrides on this page. Saving affects new runs, not one already in progress. Higher search, source, and round limits can increase processing time and consumption.
A run can take at most the clarify timeout, the plan approval timeout, and the run deadline added together. The limit is fixed when the run starts, so changing these settings later does not affect it. A run still working when it reaches the limit ends as failed and shows the reason.
Research uses the tenant's web-search integration. Its workflow is described in Deep Research.
Code sandbox
Open Administration → Tenant → Code sandbox to control the sandbox in which agents run code and preview the apps they build in Build chats. The page appears where the platform team has enabled the agent sandbox, for administrators who hold tenant.update. Through the API, reading the settings uses tenant.read and changing them uses tenant.update.
The sandbox is on by default. Sandboxes can reach the public internet over HTTPS; the site operator chooses this for the whole site. Leaving the sandbox on accepts that code the agent runs can send what it reads, such as files a member attached, to public internet services; see Security.
The same switch covers every use of the sandbox: Build chats, ordinary chats that create files, and the scripts of the Skills active in either. There is no separate switch for Skill scripts.
Turning the sandbox off for the tenant:
- stops members from running code, Skill scripts included, and previewing apps, through the Portal and the API alike, and disables Build in the Portal, with a tooltip that says the organization's administrator turned the sandbox off;
- closes open app previews at once and stops running sandboxes within about two minutes, after saving their workspaces;
- keeps earlier Build chats and their files readable.
A platform administrator can also turn the sandbox off for every tenant under Administration → Configuration; see Platform configuration. The switch on this page is then unavailable and shows that a platform administrator turned it off.
| Control | API field | Default | Accepted values | Effect |
|---|---|---|---|---|
| Code sandbox switch | enabled | true | true, false | false turns the sandbox off for the tenant. A configuration reset keeps it. |
| Largest file | max_file_size_mb | 100 | 1 to 200 | Largest single file that is saved from the sandbox or downloaded, in MB. A larger file is not saved. Applies at once, also to running sandboxes. |
| Largest workspace | max_workspace_size_mb | 1024 | 1 to 1536 | Largest saved workspace, in MB. Applies at once, also to running sandboxes. |
| Idle timeout | session_idle_timeout_seconds | 900 | More than the command timeout, up to 86400: 301 to 86400 with the default 300-second command timeout | Time without activity after which the sandbox is saved and stopped. The Portal shows it in minutes. Applies within a minute. |
| Longest run | session_hard_cap_seconds | 3600 | 300 to 86400 | Time after which a sandbox is saved and stopped, whether or not it is in use. The Portal shows it in minutes. A lower value applies within a minute, a higher one to new sandboxes. |
| App preview | preview_enabled | true | true, false | false gives the agent no app-preview tools and refuses new preview requests; open previews stay until they expire. Previews also need the deployment to provide them. |
| Preview ticket lifetime | preview_ticket_ttl_seconds | 60 | 10 to 600 | Lifetime of the single-use ticket the Portal uses to open a preview. Applies to new tickets. |
| Preview session lifetime | preview_session_ttl_seconds | 900 | 60 to 86400 | Lifetime of a preview session. Applies to new sessions. |
| App start timeout | preview_ready_timeout_seconds | 30 | 1 to 300 | How long starting an app waits for it to accept connections. |
The API checks two rules on the configuration that results from the change. max_file_size_mb must not exceed max_workspace_size_mb, and session_idle_timeout_seconds must exceed the deployment's command timeout, 300 seconds by default. A change that breaks either rule fails with HTTP 400 and error code invalid_sandbox_config, as does a request that sets sandbox to null. The storage limits are bounded by the sandbox pod's 2 GiB disk, which also holds the agent's installed packages.
Reset to defaults on the page restores the limits and leaves the switch as it is. The limits are locked while the sandbox is off.
Through the API, read the settings with GET /v1/config and change them with PATCH /v1/config and a sandbox object; follow API authentication and tenant selection. With BSQAI_BASE_URL set to https://api.<platform-domain>/v1, this request lets sandboxes stay idle for 30 minutes:
curl --fail-with-body -X PATCH "$BSQAI_BASE_URL/config" \
  -H "Authorization: Bearer $BSQAI_TOKEN" \
  -H "X-Tenant-Id: $BSQAI_TENANT_ID" \
  -H "Content-Type: application/json" \
  -d '{"sandbox":{"session_idle_timeout_seconds":1800}}'
The response contains the complete configuration after the change. Each change is recorded in the BSQAI API log with the acting user and the changed values. Site enablement, egress and sizing are covered in Enable and operate agent code sandboxes.
Authentication
Authentication is a tab of the tenant's record, not a page of the Tenant section: open Administration → Tenants, select the tenant, then open Authentication. Connect an OIDC or SAML identity provider there, complete its credential and callback setup, and configure OIDC group mappings. Follow Enterprise sign-in for setup and sign-in verification.
Access Control
Access Control groups four independently permission-gated pages for the selected tenant:
- Members — add existing accounts, create local accounts, inspect access, and remove ordinary membership.
- Groups — manage functional groups, membership, and assigned roles.
- Roles — inspect system roles and create, edit, assign, or delete custom roles.
- Service accounts — create identities for automation, assign their roles, owners and actors, and rotate their secrets.
The tenant's administrators are assigned on its record under Tenants; see Platform and tenant administrators.
Identity-management controls need both member-list and group-list permission even when the directory page itself is available with one. Functional roles, administrator authority, and resource sharing have separate permission boundaries.
System and custom roles
Follow Manage roles and permissions for the workflow. The data_admin functional role (role ID assigned_data_admin) makes an individual member a data administrator of the tenant's data catalog; see Access roles. Use the reference catalogue for exact permission IDs and fixed system-role definitions.
Collections
Open Administration → Tenant → Collections to inspect the collections created for the selected tenant's embedding and reindex cycles.
The page displays each collection's generated name and vector dimension. Selecting a row opens the dimension detail. Collection lifecycle is managed automatically; the portal does not expose manual collection creation, document inspection, similarity search, or deletion controls on this page.
Each collection name is the tenant's prefix followed by a generated suffix. The tenant's settings record the embedding model and dimension. Search and Responses API file_search use only the tenant's active collection. Foreign or inactive collection identifiers are returned as not found. Collections that neither search nor a reindex uses are deleted automatically.
The end-to-end retrieval flow is:
- General defines the embedding model, and the BSQAI API measures its dimension.
- Files ingestion writes document chunks to the managed collection.
- Collections shows the resulting collection identity and dimension.
- Chat and Service Desk retrieve context from the active collection.
See Files & RAG for the platform-level retrieval pipeline.
Theme
Open Administration → Tenant → Theme to customize the selected tenant's portal appearance.
Administrators can:
- edit independent light and dark color palettes
- review WCAG contrast warnings before applying a theme
- adjust the global border radius
- upload an SVG, PNG, or WebP logo up to 512 KB
- import CSS variables or a tweakcn registry JSON theme
- preview Theme, Chat, Files, and Agents surfaces
- reset the tenant to the default theme
Theme changes are applied to open portal tabs after they are saved. Font customization is not available because the portal uses bundled fonts for air-gap compatibility.
Service Desk
Open Administration → Tenant → Service Desk to configure the tenant's support-oriented chat entry point.
Administrators select:
- an Agent that supplies the model and system prompt
- one optional Files folder used for retrieval grounding
- whether Service Desk is enabled
An Agent must be selected before Service Desk can be enabled. The retrieval folder is optional.
The page also manages a custom icon and localized text for English, French, German, and Swedish. Each locale can define the display title, welcome message, and input placeholder. Uploading an icon opens a cropper; removing it restores the default.
At runtime, Service Desk fixes the Agent and retrieval scope chosen by the administrator. End users receive a message input without model, file-upload, RAG, or web-search controls.
Integrations
Open Administration → Tenant → Integrations to manage outbound web-search providers for the selected tenant.
The portal supports:
- Tavily
- Brave
- Exa API
- Exa (free), which needs no API key
- custom HTTPS providers
When no provider is active, web search uses the keyless Exa (free) provider.
The Web Search Providers table shows each provider's name, provider type, and creation date, and marks the tenant's active provider in the Active column. Administrators can add, edit, or delete entries. The edit dialog does not show a saved API key: leave the field blank to keep it, or enter a new value to replace it.
A custom HTTPS provider can define its endpoint, HTTP method, query parameter, authentication header, and response-field mappings.
To make a provider the tenant's active web-search provider, select its name, its row, or its Active checkbox. Activation requires tenant.provider.manage. A provider you switch away from stays saved with its credential, so you can activate it again later without deleting another provider or re-entering its key.
Allowed Resource Profiles
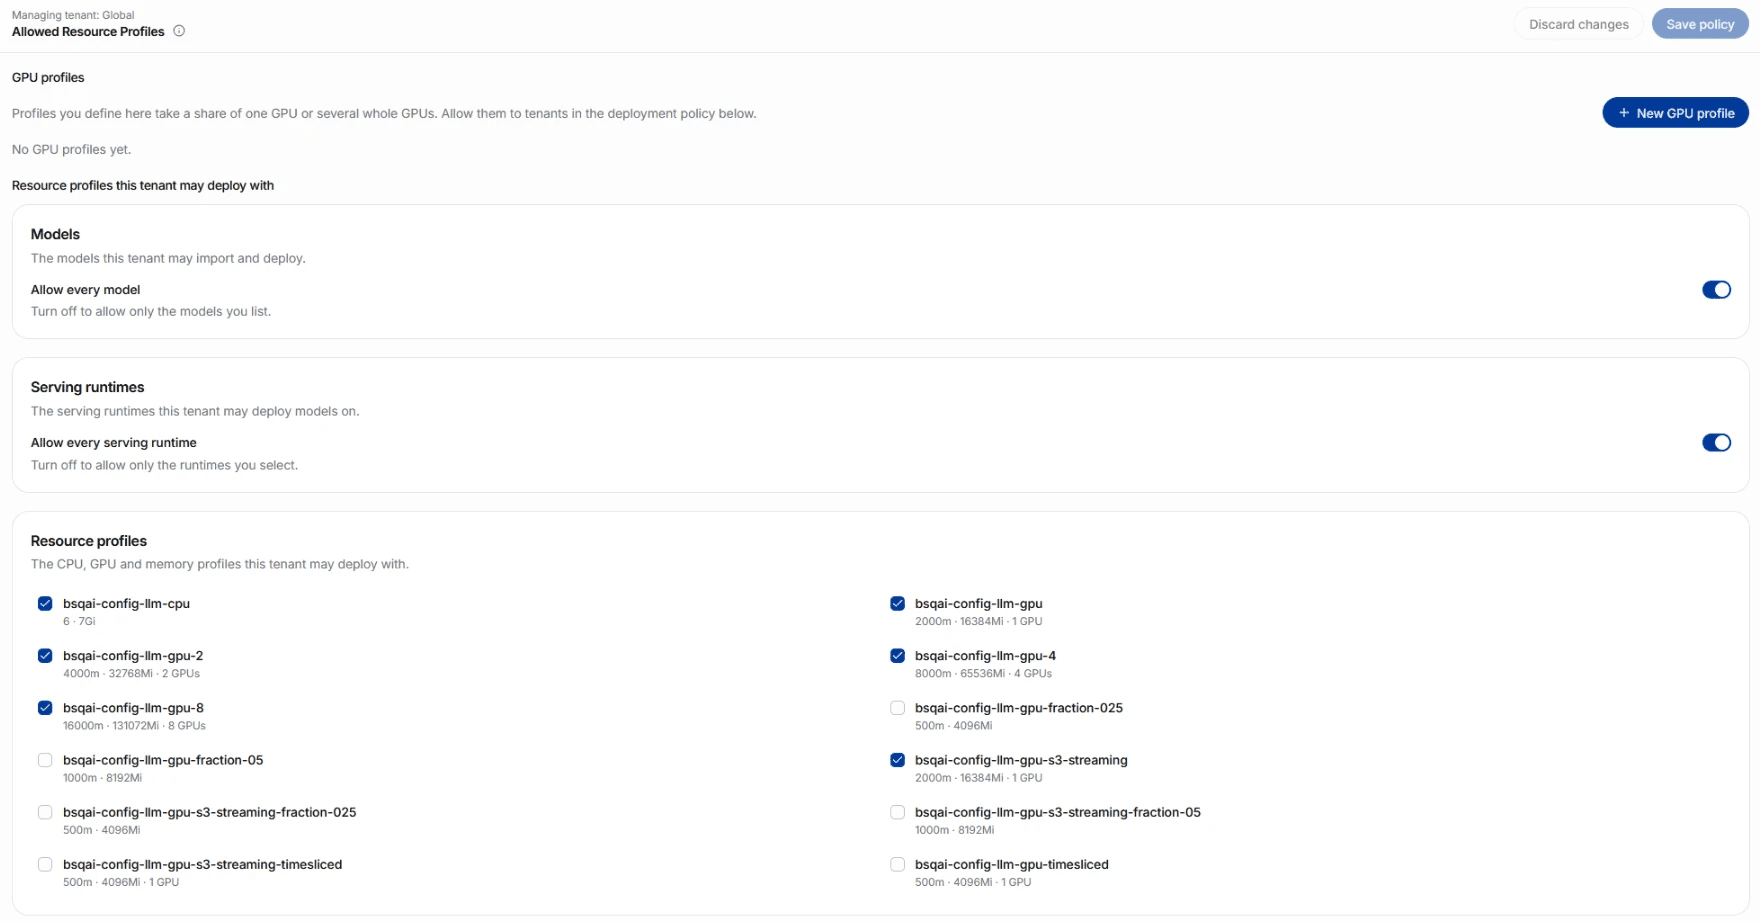
Open Administration → Tenant → Allowed Resource Profiles to see which platform-defined KServe runtime profiles the tenant may deploy with. Platform administrators decide this as part of the tenant's deployment policy; tenant administrators cannot change it.
The table supports search and shows each profile's CPU and memory, marked Enabled or Not enabled. Only enabled profiles are offered in model deployment and Model Presets. With none enabled, the tenant cannot deploy a model. The profiles themselves are defined by the platform operator and reflect the compute capacity supported by the deployment.
A platform administrator who opens this page sees the deployment policy editor for the selected tenant instead, with its models, serving runtimes, and resource profiles, and above it the GPU profiles section.
Define GPU profiles
Platform administrators, who hold platform.tenant.update, define GPU profiles at run time in the GPU profiles section of this page. A GPU profile takes a share of one GPU, or several whole GPUs. The built-in profiles stay as the platform operator configured them; see Share GPUs with time slicing and fractioning.
- Select New GPU profile.
- Enter a Name of lowercase letters, digits and hyphens, such as
h100-quarter. - Choose the kind of GPU amount, and enter its value:
- Share of one GPU: a fraction between 0 and 1, such as 0.25. Several models share the card.
- GPU memory: GPU memory in GiB on one card, such as 20. Several models share the card.
- Whole GPUs: whole GPUs on one node. Two or more serve the model with tensor parallelism.
- Optionally choose a GPU model, or keep Any GPU. The list shows the GPU models that nodes report.
- Optionally enter CPU and Memory. Left empty, the profile reserves the built-in profile's amount per GPU, scaled to this profile.
- Select New GPU profile in the dialog to save it, then allow the profile to the tenants that may use it in their deployment policy.
A new profile is allowed to no tenant until a platform administrator adds it to a tenant's policy. A profile that a tenant deployment policy still allows cannot be deleted. Models already running with a deleted profile keep running.